Choosing the right embedding model
A practical guide to embedding models, including trade-offs, evaluation methods, and retrieval quality.
Start with the task, not the leaderboard
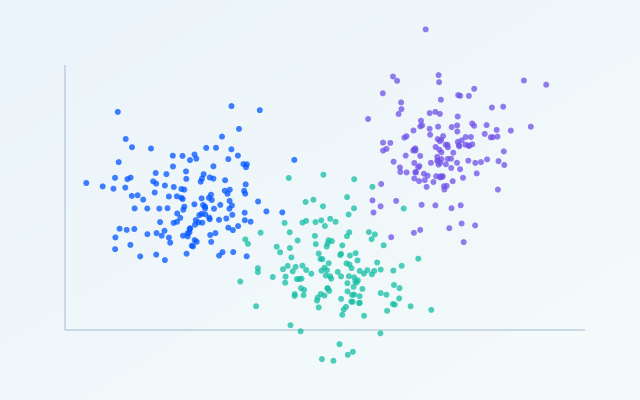
Public benchmarks rank models on average performance, but your retrieval problem is not average. Define the queries your users actually write and the documents they should find before comparing anything.
Build a small evaluation set
Collect 50–100 real queries with the documents that answer them. Measure recall@k and mean reciprocal rank for each candidate model; differences that look small on a benchmark often matter a lot on your data.
Weigh the trade-offs
Larger models improve quality but raise latency, storage and cost per query. Check embedding dimensions, maximum input length, language coverage and licence before committing, and keep the model name versioned alongside your index.